
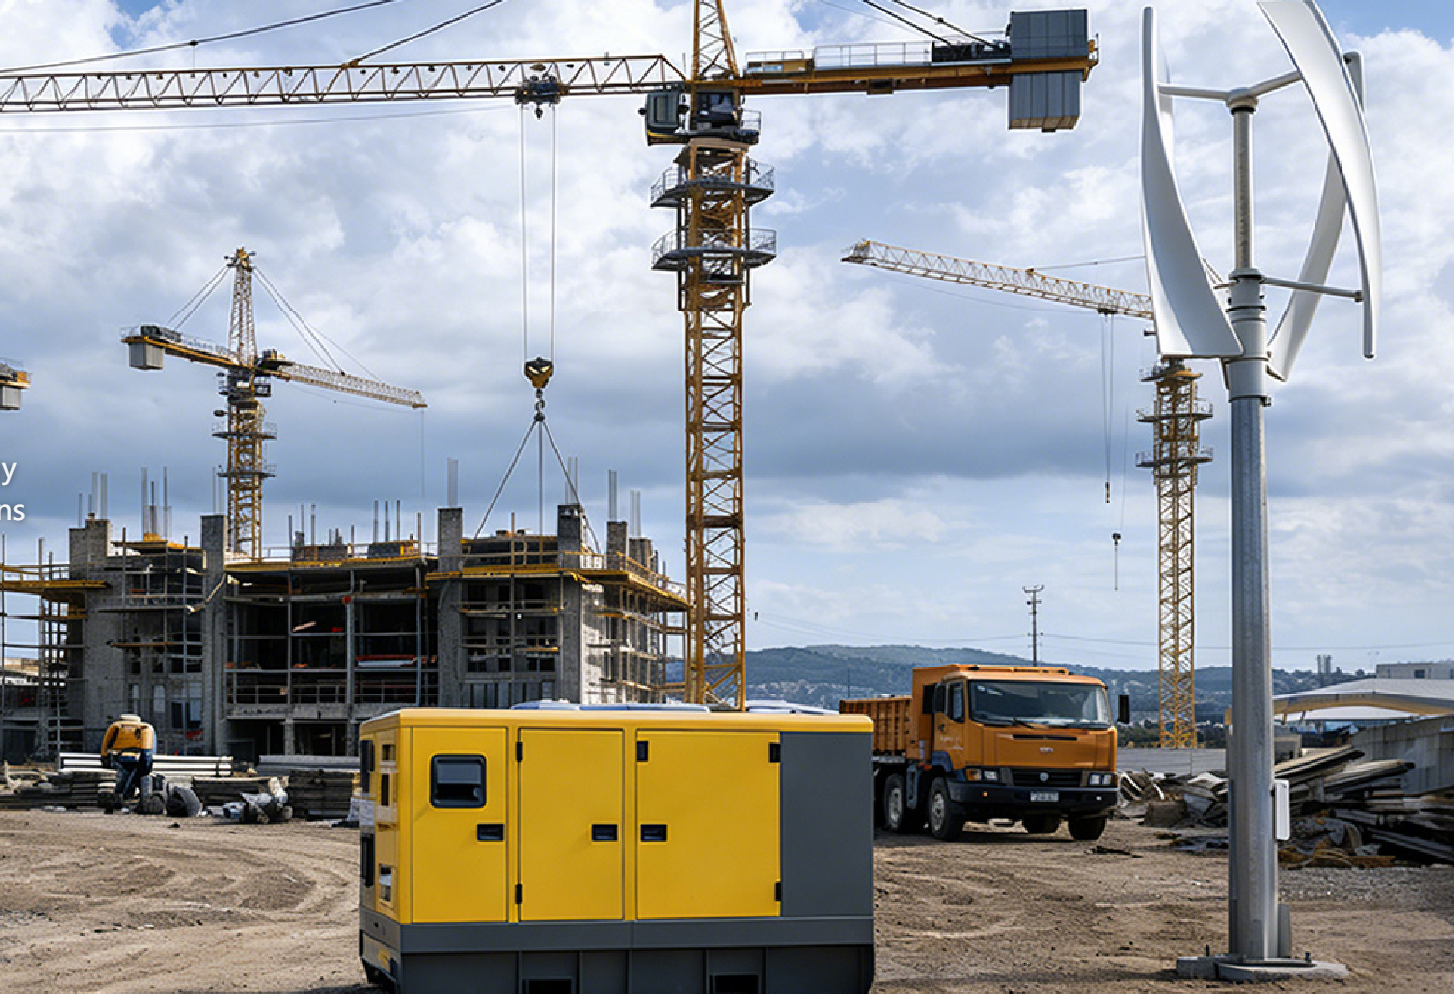
The core problem: unpredictable downtime in distributed energy
Small grids fail differently than large utilities: failures cluster, recovery is manual, and single-point fuel or control issues cascade quickly — which is exactly why an island microgrid can feel reliable one week and brittle the next. Start with that problem and design assessments that expose weak links, not comfort metrics that hide them.
Where reliability actually breaks
Focus on concrete root causes:- fuel logistics and quality failures,- control software bugs and configuration drift,- protection miscoordination and legacy relay behavior,- maintenance gaps and spare-parts shortages,- unexpected load behavior and transient interactions.Treat each cause as a test case rather than a theory.
Essential metrics that reveal true uptime
Track metrics that engineers can act on:- Availability (percent operational time) measured at the point of common coupling.- MTTR (mean time to repair) and MTBF (mean time between failures).- Successful islanding and black-start rate under scheduled tests.- Time-to-stable-state after a fault (seconds to minutes).- Fraction of energy supplied by non-fossil sources during outages.Combine long-term logs with incident-level forensic traces.
Validating resilience: tests that matter
Don’t rely on simulated dashboards alone. Run these verifications:- Planned fault injection: trip feeders, isolate DERs, validate control transitions.- Black-start drill: verify sequence from zero to stable microgrid in realistic conditions.- Load ramp stress: apply rapid load changes to observe control bandwidth.- End-to-end communications failure: force local control and validate safety behavior.Document steps, expected outcomes, and roll-back procedures for each test.
Observability, automation, and operational hygiene
Design observability like an SRE would for a cloud service:- Tiered telemetry: sub-second critical signals and minute-level trends.- Deterministic alarms and runbooks tied to alarms.- Automated remediation for common faults (safe-mode transitions, staged reconnection).- Regular configuration audits and signed firmware updates.Observability reduces guesswork; automation reduces human error.
Diesel hybrid specifics: what to inspect and why
Operational and design checks for systems that pair diesel gensets with storage are non-negotiable. Inspect fuel storage integrity, venting and bunding, and fuel-transfer reliability. Validate start sequences and governor tuning against cold-start and low-load conditions. For sites like off-grid coastal communities in the Philippines, logistical delays and corrosion are recurring constraints that shape redundancy choices. Where battery and diesel interact, verify state-of-charge strategies, charge/discharge limits, and seamless handover logic for genset-first and battery-first modes. Review the diesel storage hybrid system architecture for control hysteresis and safety interlocks.
Common pitfalls and mistakes
Avoid these traps:- Assuming a single fleet-level metric proves reliability.- Skipping realistic fuel-degradation and transport delays in planning.- Over-optimizing for steady-state efficiency at the expense of transient robustness.- Treating software updates as optional during maintenance windows.Address these now to reduce incident frequency later.
Alternatives and trade-offs
Evaluate replacements pragmatically:- Solar + storage reduces fuel exposure but adds variability and needs larger reserves.- Fuel cells and microturbines lower emissions but have different maintenance chains and capital profiles.- Pure diesel is simple but exposes supply-chain risk.Choose based on the failure modes you can tolerate and the logistical realities you face.
Action checklist for a reliability assessment
Practical steps to run an audit:- Map single points of failure and create N-1 plans.- Run three fault-injection scenarios and record recovery times.- Validate fuel-storage, transfer, and on-site maintenance capacity.- Confirm telemetry coverage for critical signals with <48-hour historical retention.- Exercise vendor-supplied control logic under local scenarios.Use findings to prioritize quick wins: configuration fixes, spare parts, and revised runbooks.
Conclusion: prioritize engineering-tested resilience
Problem-driven assessments expose what routine health checks miss: operational fragilities, logistics friction, and control-edge cases. Apply the structured metrics, tests, and maintenance practices above and you’ll turn episodic uptime into repeatable reliability — a practical outcome that a systems designer can validate against field tests and deployment experience with partners such as WidenEdge.